Alexandra Nac
Alex OS evaluation report
Alex OS answers questions about my work from what's published on this site.
This page is how I know whether it's any good: the dataset, the baselines, what I tested, what lost, and what I changed because of it. Measured 26 September 2026.
Recall@3
The right item is in the top three results for 30 of 31 labeled questions (semantic retrieval).
Mean reciprocal rank
On average the right answer is at, or very near, position one.
Answer-level evals
Passed with the language model, and passed again with it switched off.
Automated tests
On the Alex OS service, run before every change ships.
The dataset
31 questions, each paired by hand with the content item that is genuinely the right answer, checked against the corpus rather than guessed. The corpus was 140 published items. Most questions name a project, a piece of evidence or a topic directly ("insurance policy renewal assistant"); a few ask about behaviour ("is pgvector required for this system to work?").
What it doesn't cover: paraphrased questions with none of the title's words, multi-hop questions, and questions that should get "I don't know". Those need a graded-relevance set, and that's the next thing I'm building.
Experiment: does each retrieval stage earn its place?
Alex OS shipped with hybrid retrieval (semantic search fused with keyword search) plus a reranker, on by default. I had never measured whether either helped. So I ran the same 31 questions through five configurations, same corpus, same embeddings, warm caches.
- Keyword only: recall@1 87%, recall@3 97%, MRR 0.922, nDCG@5 0.942, 21 ms median
- Semantic only: recall@1 90%, recall@3 97%, MRR 0.925, nDCG@5 0.935, 4 ms median
- Hybrid (semantic + keyword, reciprocal rank fusion): recall@1 87%, recall@3 94%, MRR 0.898, nDCG@5 0.907, 27 ms median
- Semantic + deterministic reranker: recall@1 90%, recall@3 94%, MRR 0.927, nDCG@5 0.937, 46 ms median
- Hybrid + deterministic reranker (the shipped default): recall@1 84%, recall@3 94%, MRR 0.882, nDCG@5 0.896, 50 ms median
What the numbers say
- The default I shipped was the weakest configuration on this set. Fusion pulled keyword noise into questions semantic search already answered, for example pushing "Tell me about Alex OS" from rank 1 to rank 2.
- Keyword search alone is strong here because most questions contain title words. That's a bias of the dataset, not proof that keyword search is good. It's also why a harder set comes next.
- The gaps are one or two questions out of 31. That's enough to say hybrid fusion hasn't earned its place. It isn't enough to crown a winner.
- One question failed everywhere except keyword search ("WordPress platform engineering skills"): the phrase is literal, and embeddings blur it. That's exactly the case fusion is supposed to rescue, and on this set it didn't. It also lost a question semantic search had answered.
The decision
The case study no longer claims hybrid retrieval helps, because I can't show that it does. Before I switch the default, I'm running the same ablation on a graded set of paraphrased and multi-hop questions, which is where lexical fusion is supposed to earn its keep. If it doesn't win there either, it gets switched off. The evaluation harness is open source (MIT), so the metrics can be checked and reused. The Alex OS adapter that runs this exact ablation stays in the private service repository and re-runs in about a minute.
The evaluation harness on GitHubAnswer-level evaluation
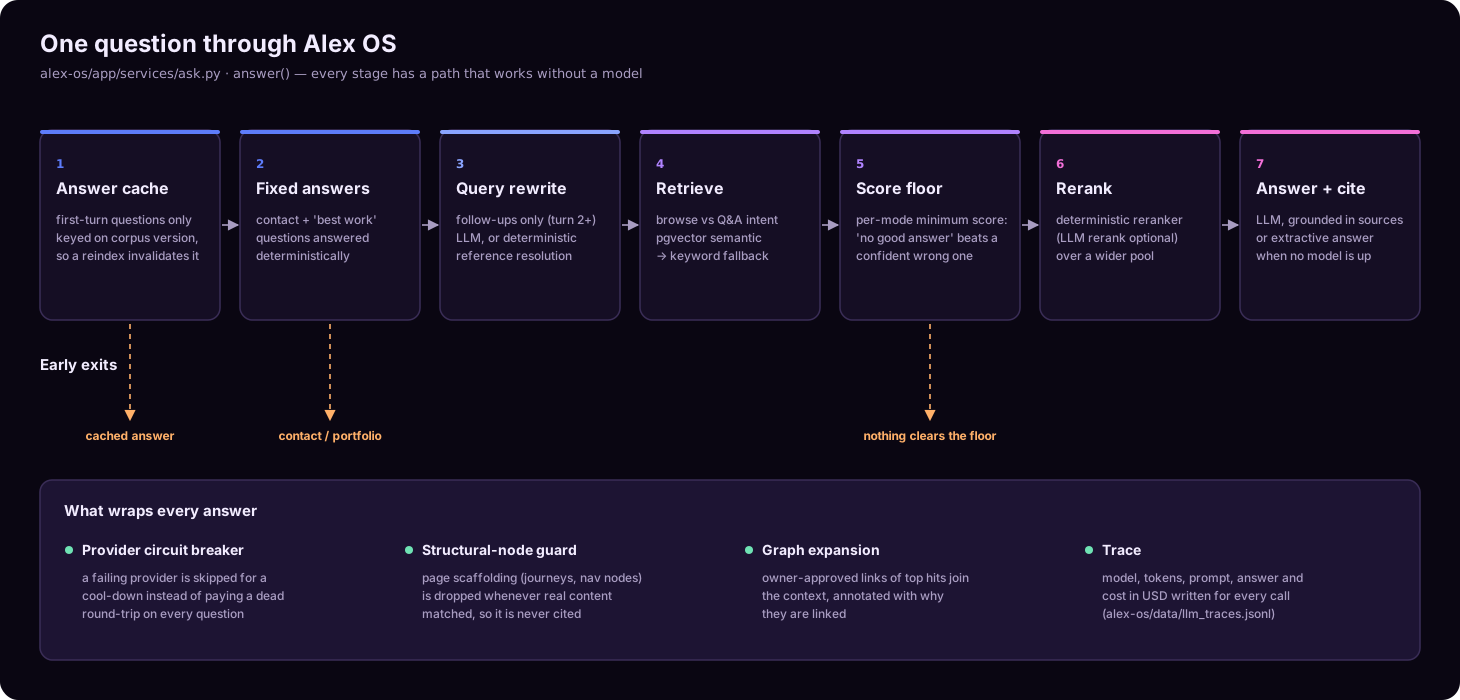
Retrieval can be right and the answer still wrong. A second set of 30 questions checks the finished answer: that it's grounded, cites real sources, never cites page scaffolding, never claims published work is missing, and says a plain "no" to questions like "does she run large Kubernetes clusters?" instead of stretching. It runs twice: once with the language model, once with the model switched off, so the fallback answer engine is held to the same standard.
- With the language model: 30 of 30 passed
- Deterministic, no model: 30 of 30 passed
Regressions these evals now guard against
- Typing "projects" returned exactly one project. Naming a content type is a browse request, not a question; retrieval now detects it and widens the net.
- The vector index was never used: a DISTINCT ON in the query forced a full scan. Found by reading the query plan, not by a symptom.
- Oversized chunks silently wiped whole embedding syncs, so parts of the site vanished from the assistant without an error.
- Career questions lost to Alex OS pages on name similarity (the right item ranked 19th to 52nd). Fixed with type affinity and by demoting navigation nodes.
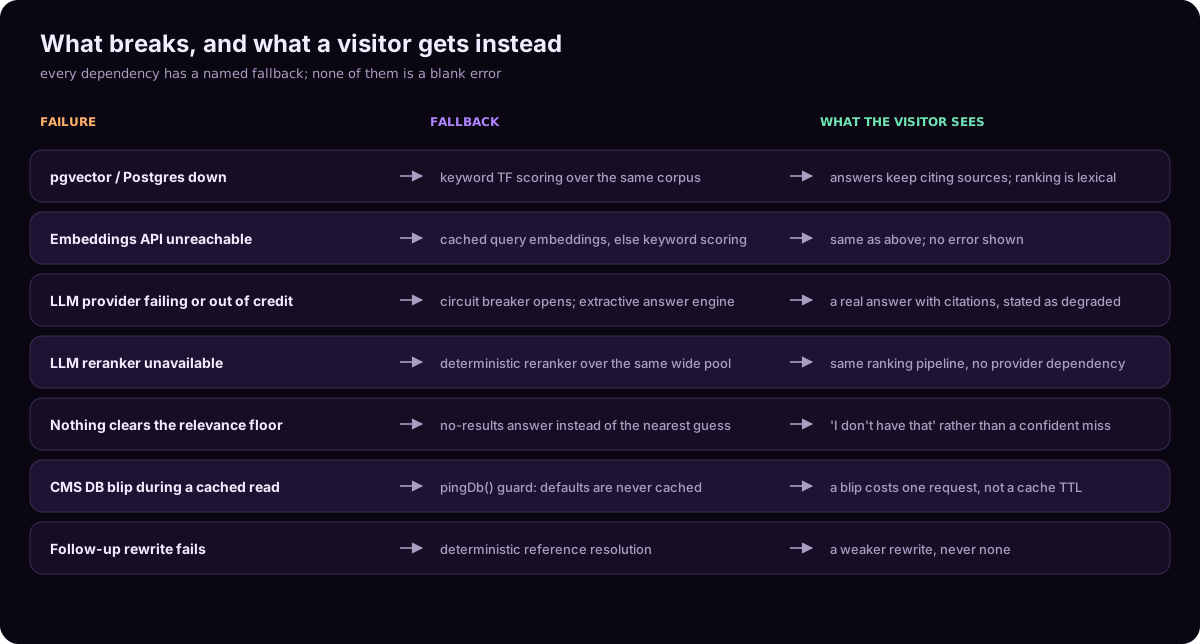
- The reranker silently stopped running when a provider key expired. It now has a deterministic fallback and a circuit breaker.
Latency and cost
- Retrieval: 4 ms median, 11 ms p95 (semantic, warm).
- A full answer with the language model: 4.0 s median, 8.3 s p95, about $0.006 per answer.
- Every model call is traced with tokens, prompt, answer and cost. That trace log is where these numbers come from: 278 answer calls recorded on my development machine between July and September.
- In the same log, 30% of answer calls failed while a provider account was out of credit. Visitors still got a cited answer from the fallback engine, and the circuit breaker now stops paying for dead round-trips.
How the system is put together
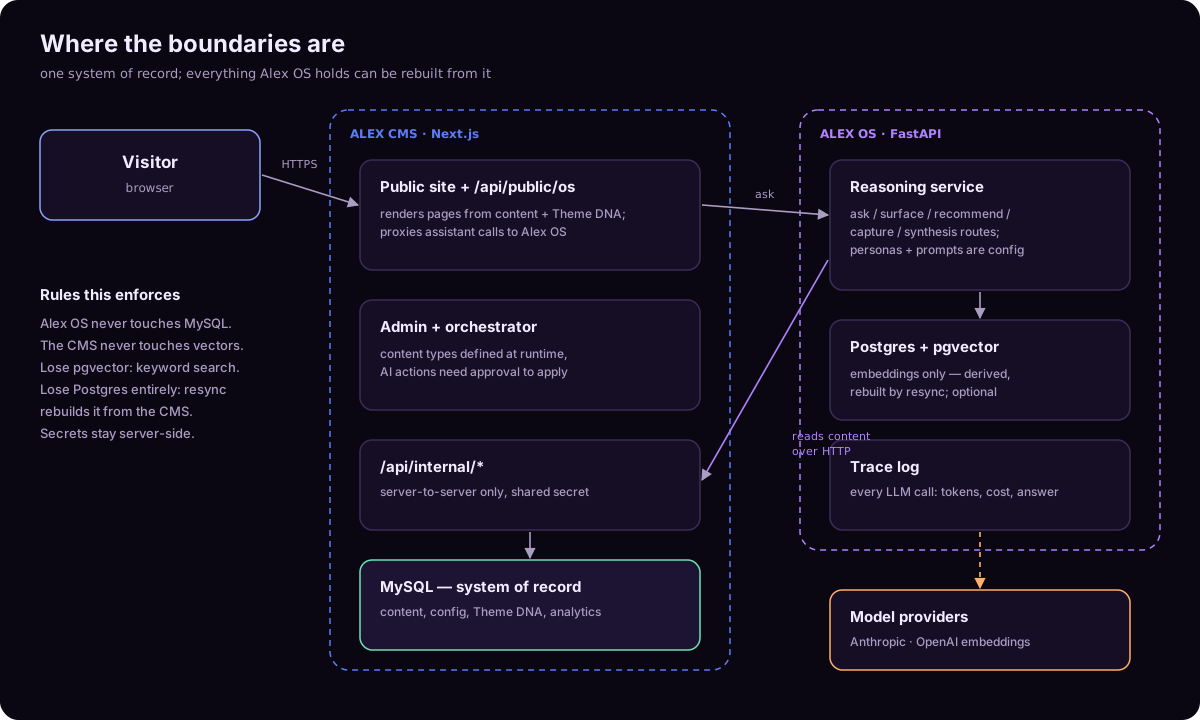
CMS — Content Registry
Next.js + MySQL
The system of record. Every content type, field, page, setting and relationship is stored in MySQL and edited through the CMS — nothing about the content model is baked into the code.
Alex OS — Reasoning Layer
FastAPI (Python)
A separate service that reads the content registry over an internal HTTP API, reasons over relationships and intent, and decides what to surface, summarize or recommend. It never touches the CMS database directly.
Retrieval — Semantic Memory
PostgreSQL + pgvector · falls back to keyword scoring
Alex OS chunks and embeds published content into its own PostgreSQL database with pgvector, so a question can be matched by meaning rather than by keyword. The vectors are derived data: they can be rebuilt from the CMS at any time, and if the vector store is unavailable retrieval falls back to keyword scoring instead of failing.
Frontend — Dynamic Experience
Next.js App Router
The public site. Journeys, sections and the assistant all render live from what the CMS and Alex OS produce, rather than from hand-built pages.
System of record: MySQL holds every content type, page, setting and relationship, and only the CMS talks to it. Alex OS keeps derived data (chunk embeddings in PostgreSQL + pgvector) that can be rebuilt from the CMS at any time, so the two databases never compete over what's true. Description verified 27 September 2026.
Limitations
- 31 and 30 cases are small. They catch regressions and large differences, not fine ones.
- I wrote and labeled the questions myself, and nobody else has validated them.
- Latency and cost come from development traffic, not production load.
- No groundedness score yet: the answer evals check citations and forbidden claims, not sentence-level faithfulness.